Work / Bezl
Bezl
A side project to make my coding agent reviews easier to follow.
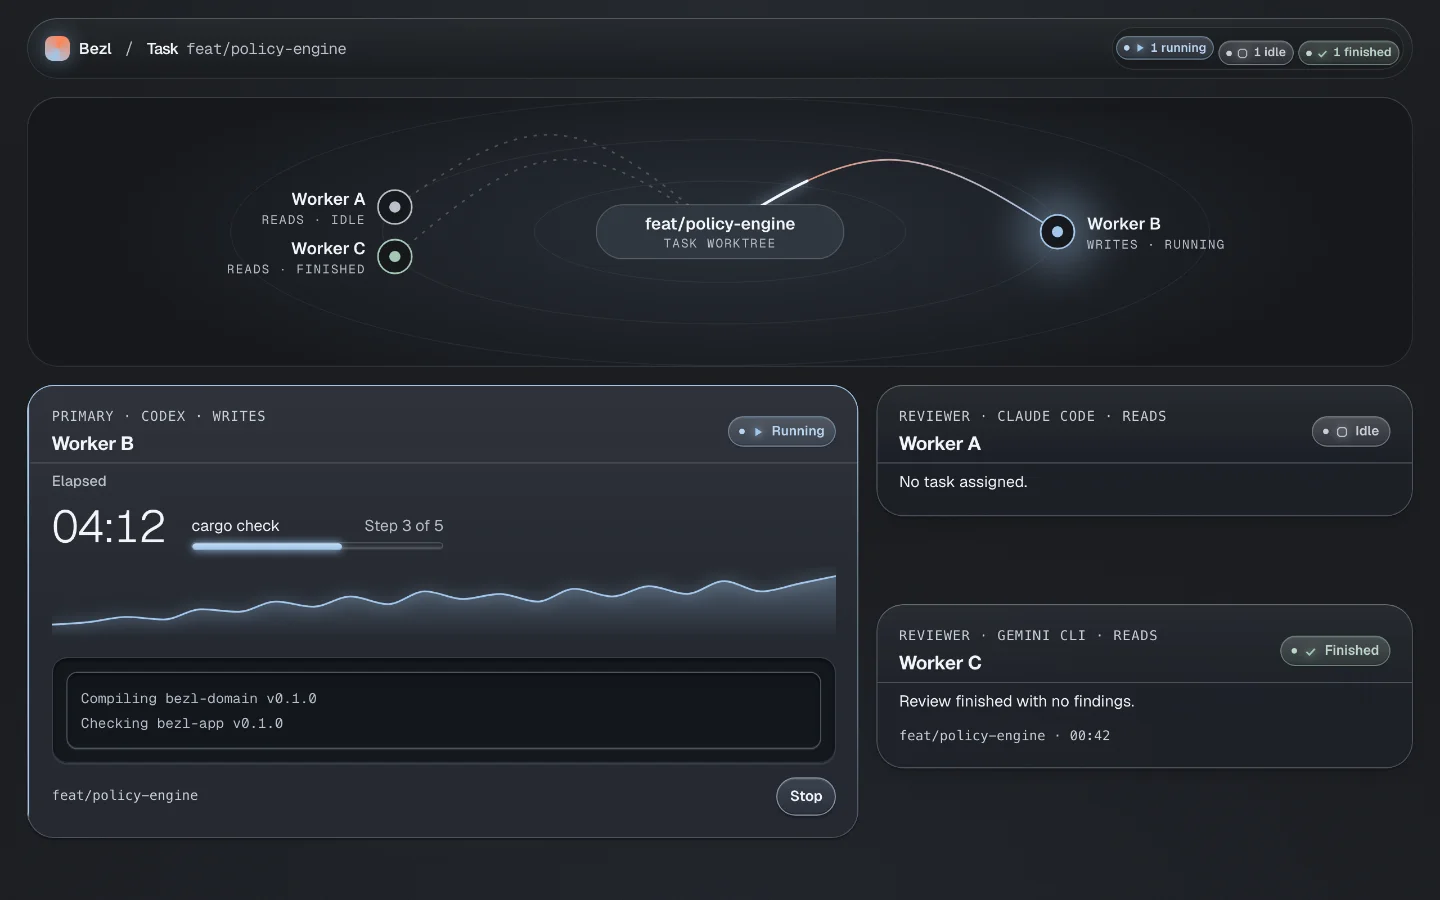
I started Bezl after a coding agent I’d asked for a review edited the patch itself. I wanted an easier way to see who changed what and which checks had run. So far, the desktop prototype has a live terminal and a task screen with sample data.
Progress
Let one agent write the patch and another review it, with the diff and check results in one place.
8 of 24 done, 1 in progress, 9 planned, 6 being rethought
Next up: First real task, end to end
Updated
The problem
I was using one coding agent to make a change and another to review it. Sometimes the reviewer would edit the same files. I’d have to work out which version it had reviewed and whether the checks still applied. I started Bezl to see how much of that handoff I could automate.
What you can try
I released v0.1.0 on 27 Oct 2026. You can open the app, use the live terminal, and explore the task screen, which is built on kbui and uses sample data. The writer and reviewer workflow is still in development.
The builds are unsigned. The release page has steps for opening them on macOS and Windows.
What I’ve tested
I tested parts of the workflow separately. The terminal stayed responsive while printing a lot of output, but memory use went over my target. I also used Ghostty’s terminal engine to capture text from a running Vim session. That test needed a specific compiler build.
In a separate test, I asked Codex in read-only mode to change a file in a scratch repo. The sandbox blocked the write.
What I’m working on
I’m working on connecting those pieces. The idea is to give one agent a separate checkout to edit, let a reviewer inspect the patch, and show me the Git diff and check results in one place.
Use of AI
I plan to use the official Codex and Claude Code command-line tools. Each would keep its own sign-in. I’m also exploring Ollama for jobs that don’t need access to the repo.
Full history
Done
Terminal snapshots from Ghostty’s engine
Ghostty's engine builds within its time budget and captures a vim screen snapshot that matches what was typed.
Done
A Codex reviewer cannot write
A read-only Codex probe is stopped by the operating system when it tries to change a file, and says so.
Done
Stack and interface foundation
kbui with the app theme is merged and passes its checks on main; the Claude reviewer probe runs under M3.
- · In progress · The stack experiments have results and the task screen runs on kbui 0.4.0, but it is not merged yet.
Done
A Claude Code reviewer cannot write
A Claude Code reviewer is refused when it tries to change a file, once Bezl launches it with read-only tools.
- · Planned · Will check that a Claude Code reviewer is refused when it tries to change a file.
Done
A test bench for agent crews
The bench has grown since its first version; all 232 tests pass and the typecheck is clean.
- · Done · It checks crew setups, gives each task its own copy of the code, stops runaway loops and compares crews with one agent.
Done
Domain core
A task's rules run in Rust: one writer per worktree, every change in a log on the clone, and the task rebuilt from that log after a crash.
- · Planned · Starts once the evidence engine's contracts are committed, without waiting for its result.
- · Planned · Will build the task rules in Rust, keep records in .git/bezl and adopt the evidence engine's contracts.
- · Planned · Will build the task rules in Rust: one writer per copy of the code, and a log that is only ever added to.
Done
Providers and preflight
Bezl finds Claude Code and Codex by their version output, checks sign-in, proves each reviewer read-only and rejects an impostor CLI.
- · Planned · Will show which agent CLIs are installed and signed in, which reviewers cannot write, and what each reports.
- · Planned · Will show which assistants are installed and signed in, and how far each can be trusted.
Done
Live terminals
Three agent terminals stream every byte, echo typing within 30 ms and stay inside the memory limits; scaling past three is next.
- · Done · Three agent terminals stream every byte, echo typing within 30 ms and stay inside the memory limits; scaling past three is next.
- · In progress · Rest memory now counts over the app's idle baseline: 4 of 5 runs meet it. Bytes, echo and snapshots pass; burst memory stays open.
- · In progress · Agent terminals stream every byte, echo typing in under 60 ms and reopen snapshots as the screen was; the memory limits stay open.
- · Planned · Will stream real agent sessions into the app without losing bytes, within the memory limits.
- · Planned · Will stream real agent sessions into Task panels within the memory limits.
In progress
Terminal output into the window
No terminal output is dropped and typing echoes with no noticeable delay; memory during heavy bursts missed the original limit.
Planned
First real task, end to end
Will take a real task from brief to pull request in the app, with evidence on Check.
- · Planned · Will take a real task through every screen, from setup to approval and evidence.
Planned
Crew in Bezl
Will add takes, model switching and handover; automatic findings to the writer only if the crew test passes.
- · Planned · Will build crews into Bezl, if the crew test passes.
Planned
Preview canvas
Split into M7a, M7b and M7c, each tracked under its own subject from now on.
- · Planned · Will let people use, point at, draw on, record and compare live previews of every take.
Planned
Recorded flows as evidence
Will turn recorded flows and accessibility checks on a live preview into checks that run after every step.
Planned
Point and Draw
Will let people point at or draw on the running app to say what to change.
Planned
The multi-take canvas
Will show every take side by side on one board, with replay and compare.
Planned
Explore with several models
Frozen until the crew test shows that a design step before coding helps.
- · Planned · Will let several models sketch design directions before any code is written.
Planned
A Gemini CLI reviewer cannot write
Will not run: Google stopped serving Gemini CLI on personal accounts on 18 June 2026, so Bezl no longer offers it.
- · Planned · Will check that a Gemini CLI reviewer is refused when it tries to change a file.
Planned
Evidence engine, second test
Narrowed to TypeScript before any branch ran; stepwise replaces LiveLeague. Other languages get their own check later.
- · Planned · Scoring settled before any branch exists; branches come from building Bezl itself.
Rethinking
A local 120B model as a third worker
Through Codex the model ran out of GPU memory on every request; called directly it answered but missed the real defect.
Rethinking
Evidence engine
Found a real problem on 6 of 10 agent branches, but two branches had too many false alarms, so the pass mark was missed.
- · Planned · Time-boxed to 6 November 2026. The first commit names the branches and the labelling rule before any code.
- · Planned · Will show whether Bezl's evidence catches real problems in agent work that the agent called done.
Rethinking
Crew test, Phase 2
Writers alone passed 35 of 36 hidden tests; a reviewer from the other provider added nothing, so M1 failed.
- · In progress · Phase 1 passed: reviewers' checked findings were real 65% of the time (bar 50%). Phase 2, the full loop, is next.
- · Planned · Scoring settled before any run; not started yet.
- · Planned · Plan tightened before any run; not started yet.
- · Planned · Redesigned before any run; not started yet.
- · Planned · Will test whether a writer and a reviewer coordinated by Bezl beat one agent working alone.
Rethinking
Terminal memory limits
The real terminal stays above both memory limits, at rest and during heavy output, though it loses no output and stays responsive.
- · Planned · Will check that the real terminal stays within new memory limits, both at rest and during heavy output.
Rethinking
A local model as a read-only Codex reviewer
A 30B local model now runs inside Codex and stays read-only, but it approved a real change with a known defect every time.
Rethinking
A Cursor CLI reviewer cannot write
Ask mode refuses the reviewer's writes, but the reviewed repo's hooks still run with no way to stop them, so Bezl does not offer Cursor.
Activity
748 commits in the last 12 weeks
| Day | Week of 19 Aug 2026 | Week of 26 Aug 2026 | Week of 2 Sep 2026 | Week of 9 Sep 2026 | Week of 16 Sep 2026 | Week of 23 Sep 2026 | Week of 30 Sep 2026 | Week of 7 Oct 2026 | Week of 14 Oct 2026 | Week of 21 Oct 2026 | Week of 28 Oct 2026 | Week of 4 Nov 2026 |
|---|---|---|---|---|---|---|---|---|---|---|---|---|
| Wednesday | 0 | 0 | 0 | 0 | 0 | 0 | 0 | 0 | 0 | 0 | 153 | 10 |
| Thursday | 0 | 0 | 0 | 0 | 0 | 0 | 0 | 0 | 0 | 0 | 108 | 0 |
| Friday | 0 | 0 | 0 | 0 | 0 | 0 | 0 | 0 | 0 | 0 | 156 | 0 |
| Saturday | 0 | 0 | 0 | 0 | 0 | 0 | 0 | 0 | 0 | 0 | 66 | 0 |
| Sunday | 0 | 0 | 0 | 0 | 0 | 0 | 0 | 0 | 0 | 0 | 0 | 0 |
| Monday | 0 | 0 | 0 | 0 | 0 | 0 | 0 | 0 | 0 | 47 | 95 | 0 |
| Tuesday | 0 | 0 | 0 | 0 | 0 | 0 | 0 | 0 | 0 | 38 | 75 | 0 |